


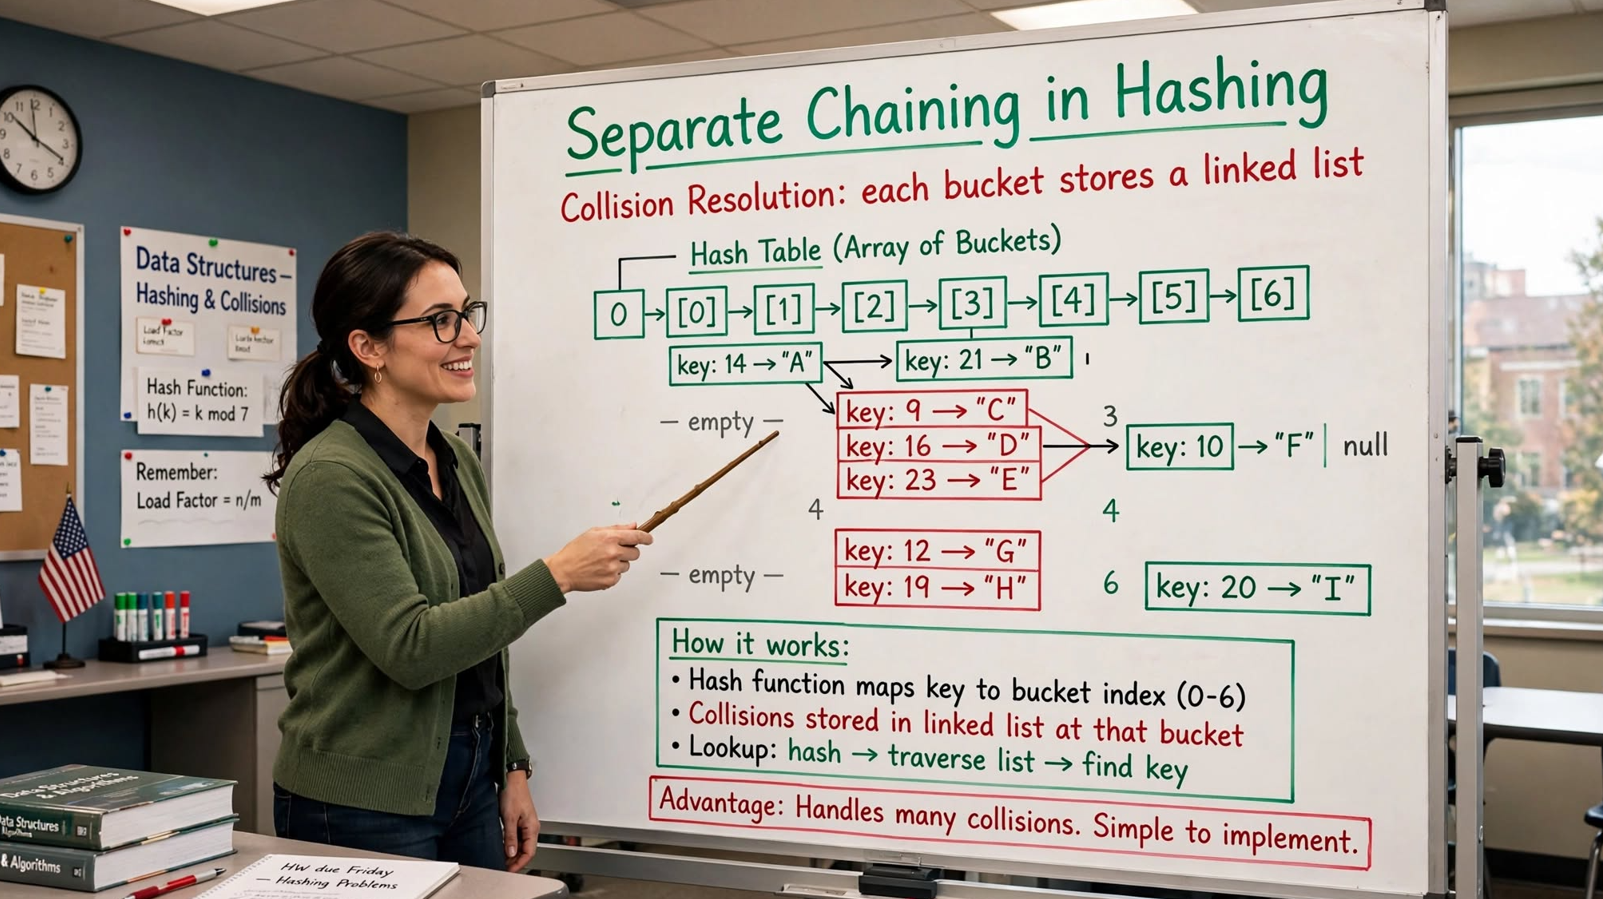
Separate Chaining in Hashing in C: Complete Guide
Separate Chaining Collision Handling Technique in Hashing in C: A Comprehensive Tutorial
Separate Chaining is one of the most popular and commonly used techniques to handle collisions in hashing. Instead of probing for an alternative slot, each bucket holds a chain (typically a linked list) of all entries that hash to the same index. This makes chaining simple, robust, and capable of handling arbitrarily high load factors.
This tutorial provides an in-depth exploration of Separate Chaining in C: fundamental concepts, data structures for chains, implementation, performance analysis, advantages and disadvantages, common pitfalls, and best practices.
Conceptual Introduction & Fundamentals
What is Separate Chaining?
Separate Chaining resolves collisions by maintaining a chain at each slot of the hash table. When multiple keys hash to the same index, they are stored in the same chain (a linked list, dynamic array, or balanced BST).
Hash function example: h(k) = k % 5
Keys [12, 22, 15, 25]:
text
12 % 5 = 2 22 % 5 = 2 (collision with 12 → add to chain) 15 % 5 = 0 25 % 5 = 0 (collision with 15 → add to chain)
Resulting table:
text
[0]: 15 → 25 [1]: (empty) [2]: 12 → 22 [3]: (empty) [4]: (empty)
Why Separate Chaining?
- Simple to implement: Just linked lists in buckets.
- Never fills up: Chains grow as needed.
- Robust to bad hash functions: Even poor distribution degrades gracefully.
- Handles dynamic workloads: Ideal when the number of keys is unknown.
- Easy deletion: No tombstones needed.
Two Main Collision Handling Methods
| Method | Description |
|---|---|
| Separate Chaining | Each slot holds a chain of entries |
| Open Addressing | All entries stored in the table itself with probing |
Performance Analysis
Under simple uniform hashing:
| Metric | Formula |
|---|---|
| Table slots | m |
| Number of keys | n |
| Load factor | α = n / m |
| Expected search time | O(1 + α) |
| Expected delete time | O(1 + α) |
| Insert time | O(1) |
If α = O(1), all operations are O(1) average.
Syntax & Core Mechanics
Data Structures for Chains
| Structure | Search | Delete | Insert | Cache |
|---|---|---|---|---|
| Linked List | O(len) | O(len) | O(1) | Poor |
| Dynamic Array | O(len) | O(len) | O(1)* | Good |
| Self-Balancing BST | O(log len) | O(log len) | O(log len) | Poor |
*Amortized; resizing may be O(len).
Java 8+ uses a Red-Black Tree for chains longer than 8 entries to bound worst-case lookup time.
Linked List Node
c
typedef struct Entry { int key; int value; struct Entry *next; } Entry; Hash Table Structure
c
typedef struct { Entry **buckets; int bucketCount; int size; } HashTable; Hash Function (Division Method)
c
static unsigned int hashIndex(int key, int bucketCount) { return ((unsigned int)key) % (unsigned int)bucketCount; } Insertion Algorithm
- Compute
idx = hash(key). - Traverse bucket; if key found, update value.
- Otherwise, prepend new node to bucket.
Search Algorithm
- Compute
idx = hash(key). - Traverse bucket list; return value if found.
- Return “not found” if chain exhausted.
Deletion Algorithm
- Compute
idx = hash(key). - Traverse bucket list tracking the previous node.
- Unlink the matching node; free it.
Full Practical Code Example with Explanation
This program implements a complete hash map using separate chaining with linked lists, supporting insert, search, delete, display, and rehashing.
c
/** * separate_chaining.c * Complete hash table using separate chaining. * Supports insert, search, delete, display, and rehashing. */ #include <stdio.h> #include <stdlib.h> #include <string.h> #include <errno.h> #define MAX_LINE_LEN 100 #define DEFAULT_BUCKETS 7 #define REHASH_THRESHOLD 1.0 /* Node in a chain */ typedef struct Entry { int key; int value; struct Entry *next; } Entry; /* Hash table with separate chaining */ typedef struct { Entry **buckets; int bucketCount; int size; int useRehashing; } HashTable; /* Division-method hash with unsigned cast */ static unsigned int hashIndex(int key, int bucketCount) { return ((unsigned int)key) % (unsigned int)bucketCount; } /* Find the next prime >= n */ static int nextPrime(int n) { if (n <= 2) return 2; if (n % 2 == 0) n++; while (1) { int isPrime = 1; for (int i = 3; i * i <= n; i += 2) { if (n % i == 0) { isPrime = 0; break; } } if (isPrime) return n; n += 2; } } /* Create a hash table */ HashTable *createHashTable(int bucketCount, int useRehashing) { HashTable *ht = malloc(sizeof(HashTable)); if (ht == NULL) return NULL; ht->buckets = calloc(bucketCount, sizeof(Entry *)); if (ht->buckets == NULL) { free(ht); return NULL; } ht->bucketCount = bucketCount; ht->size = 0; ht->useRehashing = useRehashing; return ht; } /* Free all entries and the table */ void freeHashTable(HashTable *ht) { if (ht == NULL) return; for (int i = 0; i < ht->bucketCount; i++) { Entry *cur = ht->buckets[i]; while (cur != NULL) { Entry *next = cur->next; free(cur); cur = next; } } free(ht->buckets); free(ht); } /* Rehash: grow bucket count and reinsert all entries */ static int rehash(HashTable *ht) { int newBucketCount = nextPrime(ht->bucketCount * 2); Entry **newBuckets = calloc(newBucketCount, sizeof(Entry *)); if (newBuckets == NULL) return -1; for (int i = 0; i < ht->bucketCount; i++) { Entry *cur = ht->buckets[i]; while (cur != NULL) { Entry *next = cur->next; unsigned int idx = hashIndex(cur->key, newBucketCount); cur->next = newBuckets[idx]; newBuckets[idx] = cur; cur = next; } } free(ht->buckets); ht->buckets = newBuckets; ht->bucketCount = newBucketCount; return 0; } /* Insert or update a key-value pair */ int insert(HashTable *ht, int key, int value) { if (ht->useRehashing) { double lf = (double)(ht->size + 1) / ht->bucketCount; if (lf > REHASH_THRESHOLD) { if (rehash(ht) != 0) return -1; } } unsigned int idx = hashIndex(key, ht->bucketCount); /* Update if key exists */ Entry *cur = ht->buckets[idx]; while (cur != NULL) { if (cur->key == key) { cur->value = value; return 0; } cur = cur->next; } /* Prepend new entry */ Entry *newEntry = malloc(sizeof(Entry)); if (newEntry == NULL) return -1; newEntry->key = key; newEntry->value = value; newEntry->next = ht->buckets[idx]; ht->buckets[idx] = newEntry; ht->size++; return 0; } /* Search for a key; returns 1 if found */ int search(const HashTable *ht, int key, int *outValue) { unsigned int idx = hashIndex(key, ht->bucketCount); Entry *cur = ht->buckets[idx]; while (cur != NULL) { if (cur->key == key) { *outValue = cur->value; return 1; } cur = cur->next; } return 0; } /* Delete a key */ int deleteKey(HashTable *ht, int key) { unsigned int idx = hashIndex(key, ht->bucketCount); Entry *cur = ht->buckets[idx]; Entry *prev = NULL; while (cur != NULL) { if (cur->key == key) { if (prev == NULL) ht->buckets[idx] = cur->next; else prev->next = cur->next; free(cur); ht->size--; return 0; } prev = cur; cur = cur->next; } return -1; } /* Return chain length at a given bucket */ int chainLength(const HashTable *ht, int idx) { int count = 0; Entry *cur = ht->buckets[idx]; while (cur) { count++; cur = cur->next; } return count; } /* Find maximum chain length (worst-case lookup) */ int maxChainLength(const HashTable *ht) { int max = 0; for (int i = 0; i < ht->bucketCount; i++) { int len = chainLength(ht, i); if (len > max) max = len; } return max; } /* Display the table */ void display(const HashTable *ht) { double lf = (double)ht->size / ht->bucketCount; printf("Hash Table (size=%d, buckets=%d, load=%.2f, maxChain=%d):\n", ht->size, ht->bucketCount, lf, maxChainLength(ht)); for (int i = 0; i < ht->bucketCount; i++) { printf(" [%2d]:", i); Entry *cur = ht->buckets[i]; while (cur != NULL) { printf(" (%d→%d)", cur->key, cur->value); cur = cur->next; } printf("\n"); } } /* ============ Demos ============ */ static void demoBasicChaining(void) { printf("\n=== Basic Separate Chaining ===\n"); HashTable *ht = createHashTable(5, 0); if (ht == NULL) return; int keys[] = {12, 22, 15, 25, 5, 17}; int n = sizeof(keys) / sizeof(keys[0]); for (int i = 0; i < n; i++) { insert(ht, keys[i], keys[i] * 10); } display(ht); int v; printf("\nSearch 22: "); if (search(ht, 22, &v)) printf("%d\n", v); else printf("not found\n"); printf("Search 100: "); if (search(ht, 100, &v)) printf("%d\n", v); else printf("not found\n"); printf("\nDelete 15...\n"); deleteKey(ht, 15); display(ht); freeHashTable(ht); } static void demoRehashing(void) { printf("\n=== Chaining with Rehashing ===\n"); HashTable *ht = createHashTable(5, 1); if (ht == NULL) return; for (int i = 0; i < 20; i++) { int key = (i * 13 + 7) % 100; insert(ht, key, key * 10); if (i == 4 || i == 9 || i == 19) { printf("\nAfter %d inserts:\n", i + 1); display(ht); } } freeHashTable(ht); } /* Read integer safely */ static int readInteger(const char *prompt, int *outValue) { char buffer[MAX_LINE_LEN]; char *endPtr; long val; printf("%s", prompt); fflush(stdout); if (fgets(buffer, sizeof(buffer), stdin) == NULL) return -1; errno = 0; val = strtol(buffer, &endPtr, 10); if (endPtr == buffer || (*endPtr != '\n' && *endPtr != '\0')) return -1; if (errno == ERANGE || val < -2147483647 - 1 || val > 2147483647) return -1; *outValue = (int)val; return 0; } int main(void) { int choice; char buffer[MAX_LINE_LEN]; printf("=== Separate Chaining Demo ===\n"); while (1) { printf("\n--- Menu ---\n"); printf("1. Basic Chaining Demo\n"); printf("2. Chaining with Rehashing Demo\n"); printf("3. Interactive Hash Table\n"); printf("4. Exit\n"); printf("Enter choice: "); fflush(stdout); if (fgets(buffer, sizeof(buffer), stdin) == NULL) { fprintf(stderr, "Error reading choice.\n"); return EXIT_FAILURE; } choice = atoi(buffer); if (choice == 1) { demoBasicChaining(); } else if (choice == 2) { demoRehashing(); } else if (choice == 3) { HashTable *ht = createHashTable(DEFAULT_BUCKETS, 1); if (ht == NULL) continue; int opt; while (1) { printf("\n--- Interactive Hash Table ---\n"); printf("1. Insert\n2. Search\n3. Delete\n4. Display\n5. Back\n"); printf("Enter choice: "); fflush(stdout); if (fgets(buffer, sizeof(buffer), stdin) == NULL) break; opt = atoi(buffer); if (opt == 1) { int k, v; if (readInteger("Key: ", &k) == 0 && readInteger("Value: ", &v) == 0) { insert(ht, k, v); printf("Inserted (%d → %d)\n", k, v); } } else if (opt == 2) { int k, v; if (readInteger("Key: ", &k) == 0) { if (search(ht, k, &v)) printf("Found: %d → %d\n", k, v); else printf("Key %d not found\n", k); } } else if (opt == 3) { int k; if (readInteger("Key: ", &k) == 0) { if (deleteKey(ht, k) == 0) printf("Deleted %d\n", k); else printf("Key %d not found\n", k); } } else if (opt == 4) { display(ht); } else if (opt == 5) { break; } } freeHashTable(ht); } else if (choice == 4) { printf("Exiting.\n"); return EXIT_SUCCESS; } else { printf("Invalid choice.\n"); } } return EXIT_SUCCESS; } Explanation of the Code
Entry— Node in a chain storing key, value, next.HashTable— Bucket array, bucket count, size, rehashing flag.hashIndex— Division-method hash with unsigned cast.nextPrime— Chooses prime bucket sizes.createHashTable— Allocates bucket array.insert— Prepends new node; updates existing key; optionally rehashes.search— Traverses chain linearly.deleteKey— Unlinks and frees matching node.rehash— Doubles bucket count and reinserts all entries.chainLength,maxChainLength— Helpers for diagnostics.
Expected Output (sample run)
text
=== Basic Separate Chaining === Hash Table (size=6, buckets=5, load=1.20, maxChain=3): [ 0]: (25→250) (15→150) [ 1]: (17→170) [ 2]: (22→220) (12→120) [ 3]: [ 4]: (5→50) Search 22: 220 Search 100: not found Delete 15... Hash Table (size=5, buckets=5, load=1.00, maxChain=2): [ 0]: (25→250) [ 1]: (17→170) [ 2]: (22→220) (12→120) [ 3]: [ 4]: (5→50)
Common Pitfalls, Edge Cases & Memory Considerations
1. Forgetting to Free Nodes
Each malloc must be paired with free.
c
free(cur); /* Required for every node */
2. Not Updating Duplicate Keys
Insert should update existing key, not append duplicates.
3. Integer Overflow in Hash
key * multiplier can overflow.
Solution: Cast to unsigned int before modulo.
4. Poor Cache Performance
Linked lists scatter memory.
Solution: Use dynamic arrays for chains (cache-friendly) or Red-Black Trees for large chains.
5. Long Chains
Worst-case search becomes O(n).
Solution: Rehash when load factor is high; consider RB-trees for large chains.
6. Empty Buckets Wasting Memory
Bucket array itself wastes space.
Solution: Size buckets based on expected n and target load factor.
7. Unbounded Growth
No rehashing means chains grow arbitrarily.
Solution: Use useRehashing = 1 and rehash when α > 1.
8. Unsigned vs. Signed Keys
Negative keys need careful handling.
Solution: Cast keys to unsigned int.
9. Thread Safety
Concurrent access to chains corrupts data.
Solution: Use locks per bucket or a global mutex for multi-threaded use.
10. Memory Considerations
- Bucket array:
bucketCount × sizeof(Entry *). - Each entry:
sizeof(Entry)+ malloc overhead. - Chains use more memory than open addressing.
- Free all entries and the bucket array on destruction.
Summary & Best Practices
Separate Chaining is a robust, easy-to-implement collision resolution strategy with excellent behavior for dynamic workloads. It trades memory and cache efficiency for simplicity and worst-case robustness.
Key Takeaways
- Each bucket holds a chain of entries.
- Insert at head: O(1).
- Search/delete: O(1 + α) average.
- Linked lists: O(1) insert, poor cache.
- Dynamic arrays: cache-friendly.
- RB-trees (Java 8+): O(log len) worst-case.
- Never fills up; robust to load factors.
Best Practices
- Use prime bucket sizes.
- Prepend for O(1) insert.
- Update existing keys rather than duplicating.
- Rehash when load factor > 1.
- Free every entry and the bucket array.
- Cast keys to
unsigned int. - Consider dynamic arrays for cache efficiency.
- Consider RB-trees for long chains (Java-style).
- Use djb2 or similar good hash functions.
- Profile for large datasets.
By mastering separate chaining, you’ll implement hash tables that are simple, scalable, and robust to collision-heavy workloads.